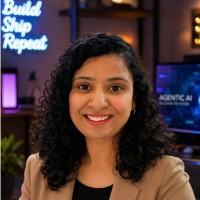
 @jothsnapraveena
Senior Data Scientist, Independent AI Researcher
Enterprise agentic AI: Jothsna, data scientist and researcher in Dallas
Hi everyone, I'm Jothsna Praveena Pendyala, a Senior Data Scientist and independent AI researcher based in Dallas. I work on an enterprise agentic AI platform. I previously worked on Amazon's Nova models.
Outside work, I'm building DeepAgentLabs and AgenticEd Academy, and I share hands-on material on GitHub, including a module-by-module Azure agentic AI build and an evals repo. My current tools are Claude Code, Codex, and Supabase. I also chair the ACM Dallas chapter.
I'd love an intro to anyone running multi-agent systems in production who has opinions on evals and observability. I'd like to compare notes on what actually holds up.
Introductions









Comments2
I'm running multi-agent GTM systems
Welcome to Lounge, Jothsna Praveena. Your focus on evals and observability for multi-agent systems in production is a hard problem, since failures often compound across handoffs. When you test these systems, do you score each agent's step on its own, or only the final outcome?
2 comments
I'm running multi-agent GTM systems
Welcome to Lounge, Jothsna Praveena. Your focus on evals and observability for multi-agent systems in production is a hard problem, since failures often compound across handoffs. When you test these systems, do you score each agent's step on its own, or only the final outcome?