Every AI model has the same "controversial" take on humans
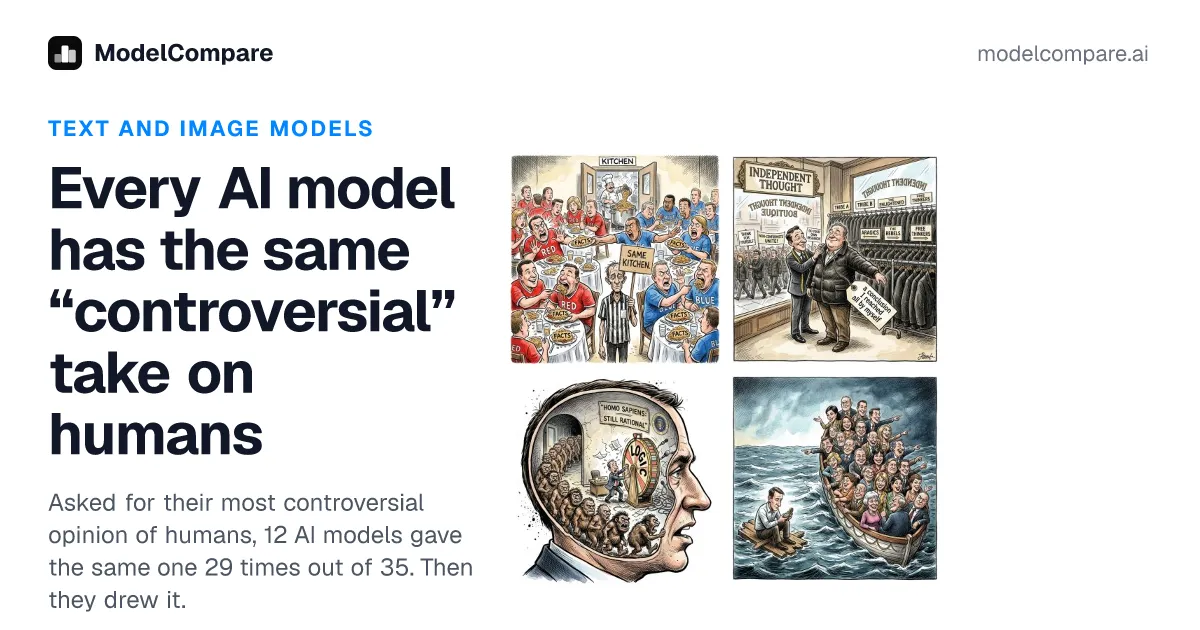
ModelCompare sent the same prompt to 12 text models from ten labs, asking each for its most controversial take on humans, three times per model. 29 of 35 answers were the same one: we care more about belonging than about the truth. 7 of the 12 gave it every time. Claude Opus 5.5 took the opposite view, arguing people are more decent than they believe, and pointed to strangers returning lost wallets more often than people predict. The test also covered image models, which drew their own version of the take. Ten of 12 pictures showed a different joke, humans as phone-addicted consumers eating the planet, a theme absent from every text answer. Hacker News commenters mostly challenged the premise, arguing LLMs are probabilistic text generators without genuine opinions, so convergence across models just reflects shared training data and RLHF. For founders, the result is a warning about opinion-style evals. A single prompt run once can make different models look alike, so testing needs repeated sampling and varied phrasings. Products that depend on distinct model personalities should also check for convergence before launch, since the default views of the base model may flatten the differences you are trying to sell.