Meta says its Prometheus cluster in Ohio will reach roughly 1 million GPUs
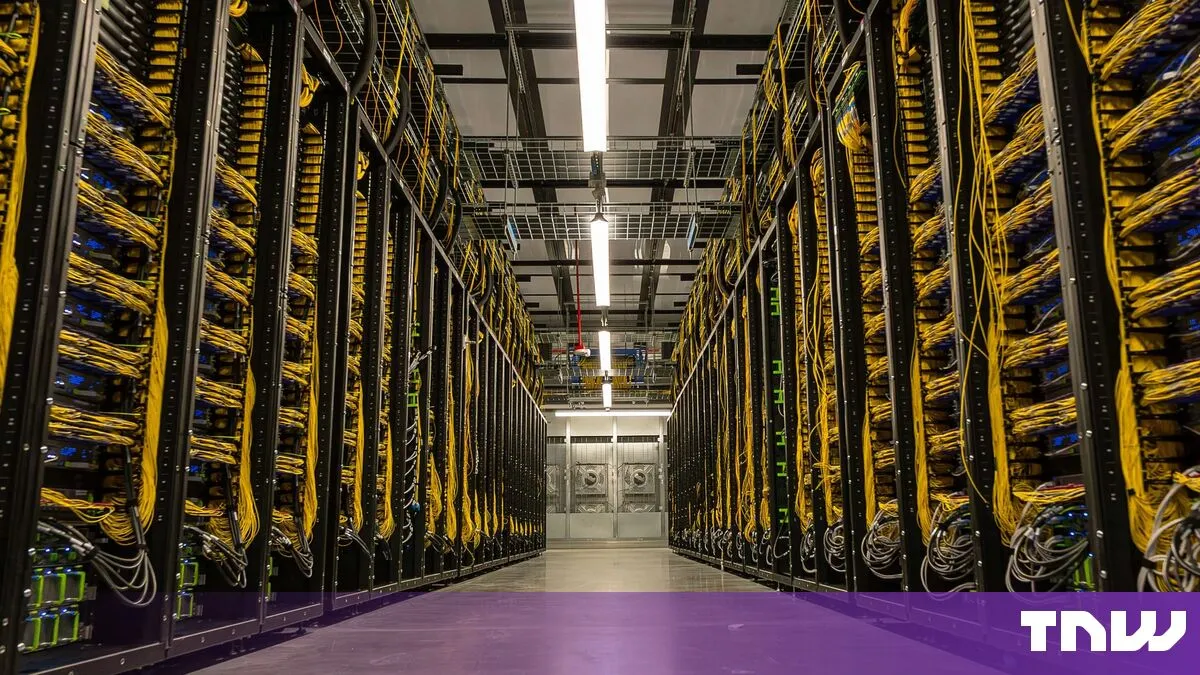
Meta says the first phase of the gigawatt-scale Prometheus site in New Albany, Ohio, has already trained its Muse models, and that the full build will run roughly 1 million distributed GPUs in lockstep. The cluster already runs hundreds of thousands of Nvidia GPUs across several buildings, with Grace Blackwell systems now and Vera Rubin racks planned. Meta also published failure data, reporting a peak of about 1,000 interruptions a day that it later reduced by 99 percent. Coverage also points to new challenges for the data center partners hosting the sites. For founders, the numbers set a reference point for frontier training infrastructure, and the reliability data is a reminder that scheduling, checkpointing and fault recovery matter as much as raw GPU count when planning compute budgets.