Latent Space: The AI Engineer Podcast · October 14, 2026 · 1h 50m

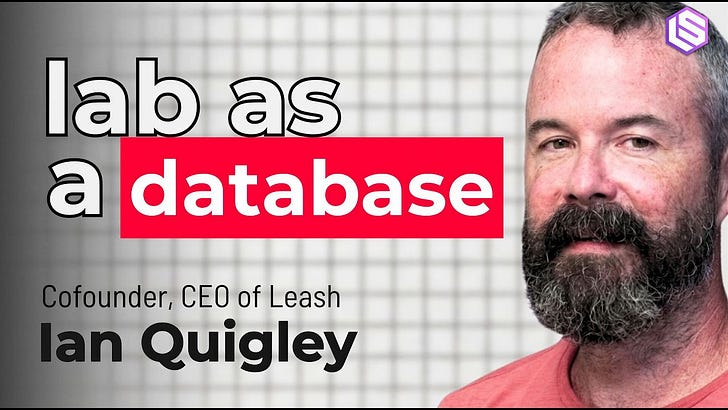
Lab-in-the-Loop at Compute Speed — Ian Quigley, Leash Bio

Show notes

A few years ago I stumbled upon Leash Bio’s Substack , and was hooked. Be it their Kaggle competition that showed that no, we really haven’t solved protein-ligand binding , or their crazy discovery that knowing a molecule’s author is perhaps all you need to know to predict how good it is . Their substack — or at least Owl Posting ’s deep dive on them — should be required reading for any scientist trying to do chemistry with AI. So I was super excited to finally be able to sit down with Ian Quigley from Leash Bio, and pick his brain. Leash specializes in DNA Encoded Libraries (aka “DELs”), a way of collecting ridiculously high-throughput interaction data between proteins and small molecules. Before I discovered Leash, I had heard nothing but horror stories from DEL users. And yet, Ian and friends somehow found a way to tame the beast, extracting clean and reproducible data that is just perfect for large scale modeling. Without teasing too much, the answer comes down to epistemic rigor, and an incredible conviction that you just have to Do The Thing. It gets even better! Near the end of this episode, Ian teases something his team was just playing with when we recorded: an AI playground for agents to do verifiable scientific reasoning. They discovered the data they had spent the last few years collecting could provide tens of thousands of “lab-in-the-loop” simulations, just what an agent needs for scientific RL. Two months later, it’s matured into Minos, and today they’re releasing a full preprint , blog , and open dataset . We’ll be releasing a lightning podcast in a few days with an update. Stay tuned! We had a blast with Ian, probably one of our most fun episodes to date. For both complete chemistry novices and expert AI x Bio practitioners, we think you’ll get something out of this. Enjoy! We covered: * Why DELs traumatize everyone who touches them, and how Leash puts dozens of barcodes on each molecule to catch proteins that bind the DNA instead of the drug. * Ian
More from Latent Space: The AI Engineer Podcast

All episodes →
Oct 13 · 1h 12m

Watch along AIE NYC and join us at AIE CODE in SF next month! This episode includes a live demo of the Taku robot that is best enjoyed on YouTube . Last month, Dyna made waves by announcing Dyna-2 , a world-action model pre-trained on one million hours of human video, claiming several new scaling laws on human data across four orders of magnitude . They have now followed up the model with a physical robot agent, Dyna-2.1 , that has to be seen to be believed: In his talk at AIE this year, Jason talked about how the real challenge for robotics in the real world is reliable, long-horizon autonomy , and how Dyna got its models to a 99.4% success rate folding restaurant napkins for 24 hours straight, including recovering after it pulled over the whole stack. From training a world-action model on over one million hours of human video to deploying robots that fold thousands of napkins daily at Din Tai Fung , Dyna Robotics is pushing physical AI beyond impressive demos and into real-world production. In this episode, Dyna Robotics co-founder and Chief Scientist Jason Ma joins swyx on-site to unpack how robots can learn new tasks from as little as 45 minutes of demonstrations, why predicting the future of the physical world may be the key to general-purpose robotics, and what it actually takes to build robots that work reliably for real customers. We go deep on Dyna-2, Dyna’s million-hour world-action model that combines future video prediction with robot actions, the scaling laws behind human-to-robot transfer, diffusion transformers and flow matching, and why synthetic environments and self-generated training data could unlock the next wave of robotics progress. Jason also explains why Dyna builds its own hardware instead of relying on off-the-shelf humanoids, how agentic harnesses enable robots to execute hour-long workflows, why dexterous hands and missing sensory data remain major bottlenecks, and what separates real commercial deployments from the graveyard of robotics

Episode page →
Oct 10 · 32 min

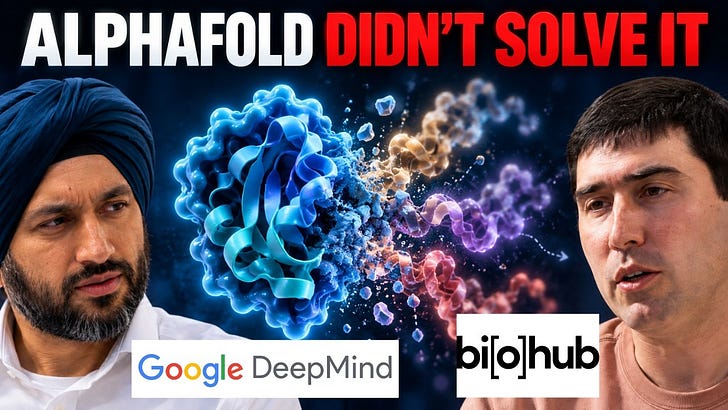
From the Bitter Lesson of AI scaling to the unsolved mysteries of protein folding , Google DeepMind’s Pushmeet Kohli and Biohub’s Sal Candido are rethinking what it takes to build AI that truly understands biology. In this special panel moderated by Brandon Anderson , they explore why AlphaFold’s breakthrough was only the beginning , why scaling compute and data alone won’t solve biology, and how the next generation of AI models could transform our understanding of proteins, cells, and human disease. We go deep on the future of AI-driven biology : finding scaling laws in biological data, the tradeoffs between scientific intuition and general-purpose architectures, why protein structure prediction is far from solved, and what it would take to build predictive models of living systems. Pushmeet reflects on the lessons behind AlphaFold , the limits of human interpretability, and whether future frontier models could understand other AI systems better than we can. Sal explains why protein language models may already contain scientific knowledge we haven’t unlocked, how biological modeling must move beyond individual proteins, and why achieving Biohub’s mission to cure all disease requires thinking in terms of 10x breakthroughs rather than incremental improvements. We discuss: * The Bitter Lesson for biology : why scaling compute and data isn’t enough * Why finding the right scaling law matters more than blindly increasing model size * How low-quality metagenomic data can improve protein language models * Why AI researchers optimize for available data instead of the most important scientific problems * Lessons from DeepMind on balancing modeling, data generation, and scientific expertise * Why building a virtual cell requires fundamentally different datasets * AlphaFold’s handcrafted architecture and the role of scientific intuition * Why good data matters more than simply having more data * Inductive biases, scaling laws, and the future of specialized AI architectures *

Episode page →
Oct 8 · 1h 24m

It’s hard to believe that Periodic was only launched last September : One year later, it is considered one of the pre-eminent AI scientist labs, with dizzying talent density and astonishing progress in the autonomous lab buildout: Most people are familiar with the standard credentials of Liam and Dogus , but we found an incredible “talent slope” while learning more about Periodic, where each successive employee seems more impressive than the last: From building AI systems that reason over noisy physical experiments to creating laboratories where every instrument can become intelligent, Periodic Labs is betting that the next frontier of AI won’t come from simply training on more internet data , it will come from letting models experiment with the real world. In this episode, Periodic Labs’ Liam Fedus and Ekin Dogus Cubuk join swyx and Brandon to explain why scientific discovery is fundamentally different from math and coding, and what it takes to build AI scientists that can actually discover new materials. We go deep on Periodic’s vision for “synthesis superintelligence” : reinforcement learning grounded in physical experiments, AI-powered materials characterization, simulations and density functional theory, high-throughput labs, and systems that learn from the entire process of doing science rather than only its published results. Liam and Dogus also explain why frontier models will still need experiments , why failed experiments may be some of the most valuable training data, what it means to give every piece of lab equipment “140 IQ,” and how autonomous experimentation could compress decades of scientific trial-and-error into months. We discuss: * Why intelligence alone isn’t enough for scientific discovery * How reinforcement learning changes when the environment is the physical world * Why science requires reasoning under uncertainty, noise, and missing information * Prediction, synthesis, and characterization in the materials discovery loop * Why physics and

Episode page →
Oct 2 · 1h 41m

Last call for regular tickets for AI Engineer NYC ! As an exclusive for Latent Space subscribers, the first 30 of you can take a 30% off code if it helps - for new tickets only, no refunds! See you in 2 weeks! While we tend to cover industry on the pod, every so often we celebrate a clearly emerging superstar PhD. In 2024 we featured Shunyu Yao , who went on to build Operator at OpenAI and is now Chief AI Scientist of Tencent . In 2025 we featured Jack Morris , who went on to cofound Engram at $600m and is now a leading voice on continual learning . This year we are proud to feature the work of Alex Zhang of MIT. From GPU kernels and KernelBench to Recursive Language Models , Mismanaged Geniuses , and massive multi-agent swarms, Alex Zhang is exploring how much capability we’re leaving on the table by wrapping increasingly powerful models in primitive systems. RLMs took over the timeline early this year: and an RLM based harness was the first to ~solve ARC-AGI-3 before OpenAI’s Astra: and is even today, influencing new research that has more extreme implications than RLMs: We go deep on GPU Mode and AI-written kernels, research taste and why academics should take bets industry labs won’t, GEV and alternatives to the standard autoregressive language model, and the idea of harnesses as compositional generalizers. Alex explains RLMs, context offloading, programmatic subagent calling, Prime Agent, persistent subagents, and why the “language model” of the future may actually be an invisible swarm of agents underneath a simple interface. We also discuss OpenAI’s massive agent experiments, Kimi swarms, open-ended research at Sakana AI, speculative programmatic tool calling, capability overhang, Neuralese, and where Alex thinks the next big research opportunities may lie. We discuss: * Why AI-generated GPU kernels still leave substantial room for human expertise * How one expert insight can potentially replace enormous amounts of brute-force token search * Why PhD students

Episode page →
Sep 30 · 39 min

Three months ago Dwarkesh, who has been posting incredible blogs and episodes about RL, posted a framing question for his video essay on RLVR which upset a lot of Computer Use folks: We are no strangers to learning in public and are no strangers to the stress of getting things wrong when you have a big platform. However, we were at Anthropic for the Computer Use launch , there for Claude Cowork with the first big podcast on it, organized the first Computer Use track at AIE presenting the state of the art, and were close to the OpenAI-Sky Software acquisition that now powers the complete domination of computer use that Codex enjoys today. This is why we’re excited to bring you today’s first guest, Ari Weinstein , cofounder of Sky and now leading all the amazing CUA progress that casuals might miss: Ari explains why Computer Use is now “180 degrees different” from where it was months ago, how agents are learning to debug and recover from failures, why combining screenshots with accessibility data, the DOM, Playwright, and generated code changes the speed equation, and why the next frontier is making agents literally superhuman at using software. OpenAI clones Jev In the second half, Nikunj Handa from OpenAI’s API team breaks down the new developer stack: async tool calling, mid-turn steering, WebSockets, UltraFast inference, the Decisions API, prompt caching, pre-warming, compaction, and the Agents API . Given that we were the first Jev podcast , we particularly focus on the unusually fast sprint on the Decisions API: And why it is just a Luna wrapper for now but the team is motivated and egoless enough to clone what they consider to be good patterns. We discuss: * Why OpenAI thinks Computer Use has changed dramatically in just the last few months * Dots and what changes when every agent gets its own Linux computer * Why Computer Use can now complete some tasks faster than the average human * The path from human-level to “literally superhuman” computer use * Why moder

Episode page →
Sep 29 · 1h 32m

We are excited to have Anthropic share their latest AI x Finance work at AI Engineer New York , coming up in 2 weeks! In case you’ve been under a rock, here’s a non-exhaustive list of what Anthropic has been shipping since closing the largest fundraise of all time in May at $47B ARR: * June: Launched Claude Tag and Sonnet 5 and Fable 5 * July: Opus 5 , /checkup . crossed $65B ARR * Last month: Fable/Mythos 5.1 , and EFS (upcoming pod) * IPO target $2T , end 2026 ARR estimated $100B * Cowork/chat merged before did * Claude Mods * Dario endorses the same Pacing the Frontier message cosigned by all labs * Last week: Opus 5.5 , Plugins portal , Cloud Sessions/ Claude Projects * Today: Sonnet 5.5 ! Today’s episode should catch you up, with Thariq Shihipar , the explainer-king of Anthropic, who we last caught up on Fable launch day with The Field Guide to Fable : The Future of Mutable Software Pay special attention to Claude Mods (especially the cheatsheet ): In general this is also the inverse of the other viral tweet from Thariq: Cloud Brain, Local Hands And give a try to Claude Projects : The “hands” terminology is not just an analogy for the local/cloud paradigm that is being built up at frontier coding agent companies like Cognition , but is ALSO particularly relevant to the safety systems discussions that we’ll be discussing with Anthropic in an upcoming episode as they prepare to pace to frontier with responsible AI deployment. For those who want Thariq’s writing tips we teased at the start of the pod, watch the full video here: From the rapid rise of Claude Code to a future where agents can rewrite their own harnesses, collaborate across teams, and operate across cloud and local environments, the way we build software is changing extraordinarily fast. In this episode, Anthropic’s Thariq Shihipar joins swyx and Vibhu to unpack how power users are actually working with Claude Code today , why prompting remains a high-skill discipline, and where Anthropic thinks the

Episode page →